
Using GPUs with Fuzzball
Fuzzball intelligently passes GPU resources from the host through to the containers that support your jobs. Once an administrator has properly added and configured resources that include GPUs, request them in your Workflow.
Observe the following Fuzzfile:
version: v4
jobs:
  gpu-check:
    image:
      uri: docker://rockylinux:9
    script: |
      #!/bin/sh
      nvidia-smi
    resource:
      cpu:
        cores: 1
      memory:
        size: 1GB
      devices:
        nvidia.com/gpu: 1
Note that the gpu-check job in this workflow is based on the official Rocky Linux (v9) container
on Docker
Hub.
This container does not have a GPU driver or any NVIDIA related software installed. However, the
Fuzzfile specifies that this job should run the program nvidia-smi to check the status of any GPUs
that are present.
The job’s resource section has a devices field for requesting GPUs. The administrator in this
example configured GPUs under the name nvidia.com/gpu, so the job asks for one of those.
Fuzzball makes the driver-related software available in the
container.
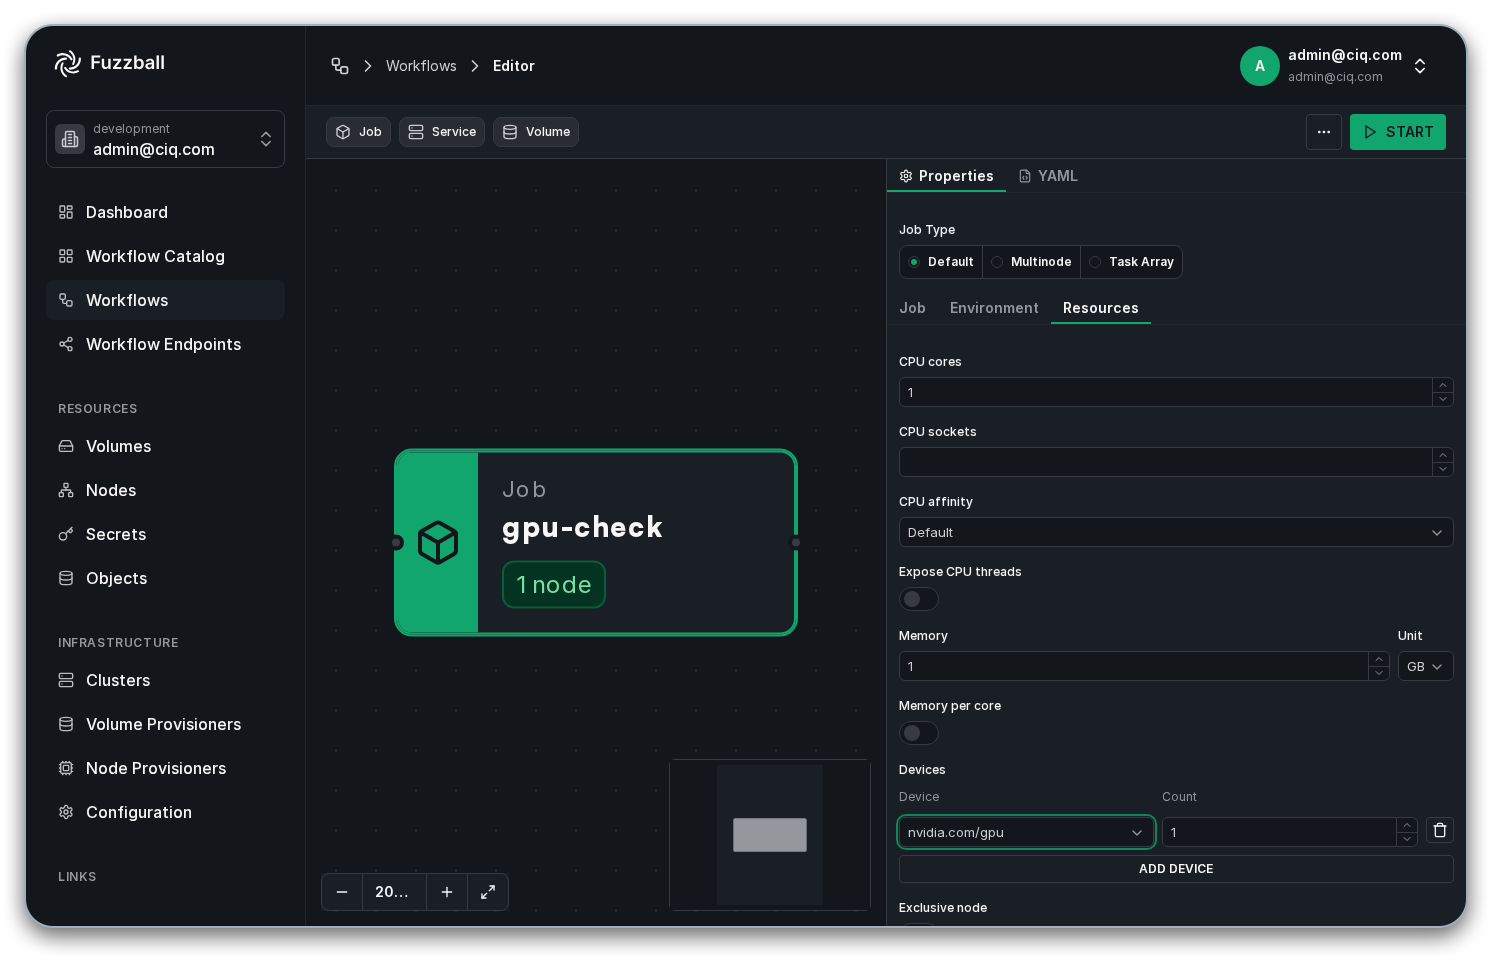
If you are using the workflow editor in the web UI to create your Fuzzfile, select the job, open the
Resources tab of the Properties panel on the right, and click ADD DEVICE. That adds a
Device / Count pair; choose the device from the Device drop down and set how many the
job needs. Once again, in the example configuration, the nvidia.com/gpu device is the appropriate
one to add a GPU to our job.
After submitting the workflow, note that the nvidia-smi command has no trouble completing even
though the Rocky Linux container has no NVIDIA-related software.
Thu Feb 12 18:13:24 2026
+-----------------------------------------------------------------------------------------+
| NVIDIA-SMI 590.44.01              Driver Version: 590.44.01      CUDA Version: 13.1     |
+-----------------------------------------+------------------------+----------------------+
| GPU  Name                 Persistence-M | Bus-Id          Disp.A | Volatile Uncorr. ECC |
| Fan  Temp   Perf          Pwr:Usage/Cap |           Memory-Usage | GPU-Util  Compute M. |
|                                         |                        |               MIG M. |
|=========================================+========================+======================|
|   0  Tesla T4                       Off |   00000000:00:1E.0 Off |                    0 |
| N/A   23C    P8              8W /   70W |       0MiB /  15360MiB |      0%      Default |
|                                         |                        |                  N/A |
+-----------------------------------------+------------------------+----------------------+

+-----------------------------------------------------------------------------------------+
| Processes:                                                                              |
|  GPU   GI   CI              PID   Type   Process name                        GPU Memory |
|        ID   ID                                                               Usage      |
|=========================================================================================|
|  No running processes found                                                             |
+-----------------------------------------------------------------------------------------+
It’s important to understand that not only is installing GPU drivers within your containers unnecessary for GPU workflows, it’s actually considered a poor practice that can lead to compatibility issues. Here’s why:
When executing GPU workloads, Fuzzball automatically identifies the appropriate libraries and binaries associated with the GPU driver installed on the host system and dynamically injects them into your container at runtime. This sophisticated mechanism ensures perfect compatibility between the kernel modules running on the host and the libraries available inside the container.
If you manually install GPU drivers inside your container, you risk creating conflicts — the software in your container might discover and attempt to use these drivers instead of the properly injected ones, potentially disrupting the correspondence between libraries and kernel modules and leading to mysterious failures or performance issues.
Important distinction: There is a difference between the GPU driver and libraries like CUDA or HIP. This is confusing since CUDA and HIP are often packaged with their corresponding GPU drivers. While you should not install GPU drivers in your container, you should install the appropriate computational libraries to support your GPU-accelerated applications.
Fuzzball supports AMD ROCm GPUs using the same device-plugin mechanism as NVIDIA, with the
amd.com/gpu device string. The device plugin passes the GPU device nodes (/dev/kfd and
/dev/dri/renderD*) through to your job and makes the host’s ROCm driver libraries available in the
container. Request one by adding
amd.com/gpu under resource.devices (or via the Resources tab in the web UI workflow editor, the
same way you would add nvidia.com/gpu):
version: v4
jobs:
  amd-gpu-details:
    image:
      uri: docker://python:3-slim
    script: |
      #!/usr/bin/env python3
      import glob, os

      def read(p):
          try:
              with open(p) as f:
                  return f.read().strip()
          except OSError:
              return None

      NAMES = {"0x1586": "AMD Radeon 8050S/8060S (Strix Halo, gfx1151)"}
      found = False

      for dev in sorted(glob.glob("/sys/class/drm/card*/device")):
          if read(f"{dev}/vendor") != "0x1002":
              continue
          found = True

          did = read(f"{dev}/device") or "unknown"
          print(f"GPU      : {NAMES.get(did, 'AMD GPU')} [{did}]")
          print(f"PCI addr : {os.path.basename(os.path.realpath(dev))}")

          # Read strict hardware buffer
          vt = read(f"{dev}/mem_info_vram_total")
          vu = read(f"{dev}/mem_info_vram_used")

          # Read flexible system memory pool (GTT) used by ROCm/AI
          gt = read(f"{dev}/mem_info_gtt_total")
          gu = read(f"{dev}/mem_info_gtt_used")

          # Calculate Total Unified Memory Available to your AI Code
          total_vram = (int(vt or 0) + int(gt or 0)) / 2**30
          used_vram = (int(vu or 0) + int(gu or 0)) / 2**30

          print(f"Unified VRAM Total : {total_vram:.1f} GiB (Dedicated: {int(vt or 0)/2**30:.1f} GiB + GTT: {int(gt or 0)/2**30:.1f} GiB)")
          print(f"Unified VRAM Used  : {used_vram:.2f} GiB")

          busy = read(f"{dev}/gpu_busy_percent")
          if busy is not None:
              print(f"GPU busy : {busy}%")

          for hw in glob.glob(f"{dev}/hwmon/hwmon*/temp1_input"):
              t = read(hw)
              if t:
                  print(f"Temp     : {int(t) / 1000:.0f} C")

          print()
          print("READY" if os.path.exists("/dev/kfd") else "NOT READY: /dev/kfd missing")

      if not found:
          print("No AMD GPU visible in /sys/class/drm -- is /sys mounted in the job?")
    resource:
      cpu:
        cores: 1
      memory:
        size: 1GB
      devices:
        amd.com/gpu: 1
This job reads the GPU’s attributes from sysfs – name, VRAM, utilization, temperature, and PCI
address – and confirms that /dev/kfd is present, indicating the GPU is passed through and ready
for ROCm workloads.
Unlike NVIDIA – where the hostnvidia-smiis injected and runs in a stock container image – AMD’srocm-smiis a Python-based tool that is not injected. To run ROCm applications or inspect the GPU withrocm-smi/rocminfo, use a container image that ships its own ROCm userspace (for example arocm/*image). As with NVIDIA, do not install the GPU driver itself inside the container.
On systems with Multi-Node NVLink (MNNVL), the GPUs of several nodes share one NVLink domain. Jobs can use NVLink between those nodes through NVIDIA IMEX, which Fuzzball does not run itself. For each NVLink domain:
Run the
nvidia-imexservice on every node, with/etc/nvidia-imex/nodes_config.cfglisting the domain’s nodes. The file must be identical on every node, and changing it means restartingnvidia-imexon all of them.Create IMEX channel 0, either by loading the
nvidiakernel module withNVreg_CreateImexChannel0=1or by hand:$ major=$(awk '$2 == "nvidia-caps-imex-channels" {print $1}' /proc/devices) $ sudo mkdir -p /dev/nvidia-caps-imex-channels $ sudo mknod -m 666 /dev/nvidia-caps-imex-channels/channel0 c "$major" 0Job users must be able to read and write the channel: a job gets the access the file’s mode grants its user and group. Check that
ls -l /dev/nvidia-caps-imex-channels/channel0showscrw-rw-rw-.Install version 0.0.20 or later of the
fuzzball-substrate-nvidia-gpu-pluginpackage.Confirm the domain with
nvidia-imex-ctl -N: every node should beREADY, withCin the connectivity table.
With the plugin installed, each node reports its NVLink domain as the node annotation
nvidia.com/gpu.clique. The scheduler uses it to place each multinode job inside one domain
whenever one has enough free nodes, and spans domains when none does. The annotation is for the
scheduler only and is not stored on provisioner definitions, so jobs cannot use it to pick a
domain. The plugin reads the domain when substrate starts, waiting up to 30 seconds for the GPUs
to register with the NVLink fabric.
After the NVLink domains change, or if a node started before registration finished, run
systemctl restart fuzzball-substrate.service on the affected nodes.
Every job that uses channel 0 in an NVLink domain shares it, so a job can read GPU memory that another job in the same domain shares through IMEX. Treat each NVLink domain as one trust domain.
Users request the channel in their Fuzzfile; see Multi-Node NVLink.
Fuzzball collects per-device health alongside the device inventory above and reports it. Whether a failing card takes its node out of service is a monitoring decision: an alerting rule matching the counters below places a hold, and the hold is what stops work being placed there. NVIDIA and AMD devices report through the same collector.
On NVIDIA nodes the collector reads ECC error counts, Xid faults from the kernel log, and
thermal or power throttling reported by the driver. Nothing extra needs installing: it uses the
nvidia-smi that ships with the driver, and a node without it reports GPU health as unavailable
rather than as an error.
On AMD nodes the collector reads the amdgpu driver’s RAS error counters and hwmon
temperatures directly from sysfs, so only the kernel driver is required — the ROCm userspace does
not need to be installed. Every temperature channel the card exposes is read — edge, junction and
memory — and each is compared against its own critical value, so a hot junction is caught while the
edge reading is still low. Three differences from NVIDIA are worth knowing:
There is no AMD equivalent of an Xid fault, so that condition never applies to an AMD device.
The driver publishes no “clocks are being held down” attribute, so thermal throttling is inferred from a channel reaching the driver’s own critical temperature rather than reported by it.
AMD RAS counts deferred errors separately: an uncorrectable error found in data nothing had read yet, which the driver handles by retiring the memory. Those raise a warning rather than a critical condition, since nothing was corrupted, but they are never reported as a clean card.
Whether a warning takes the node out of service is a monitoring decision, not a Fuzzball one: write an alerting rule carrying
fb_action: evictif deferred errors should evacuate the node.
A card whose hardware exposes no RAS counters reports ECC as unavailable rather than as zero errors, so an uninstrumented card is never mistaken for a healthy one. The same holds for temperature: a card that publishes readings but no critical threshold reports thermal health as unavailable, since there is nothing to judge the reading against.
GPU counters are exported by DCGM Exporter on the node and evaluated by your monitoring stack. See Node Health Monitoring for how Fuzzball publishes node facts and how a rule takes a node out of service.